01
Connected device platform
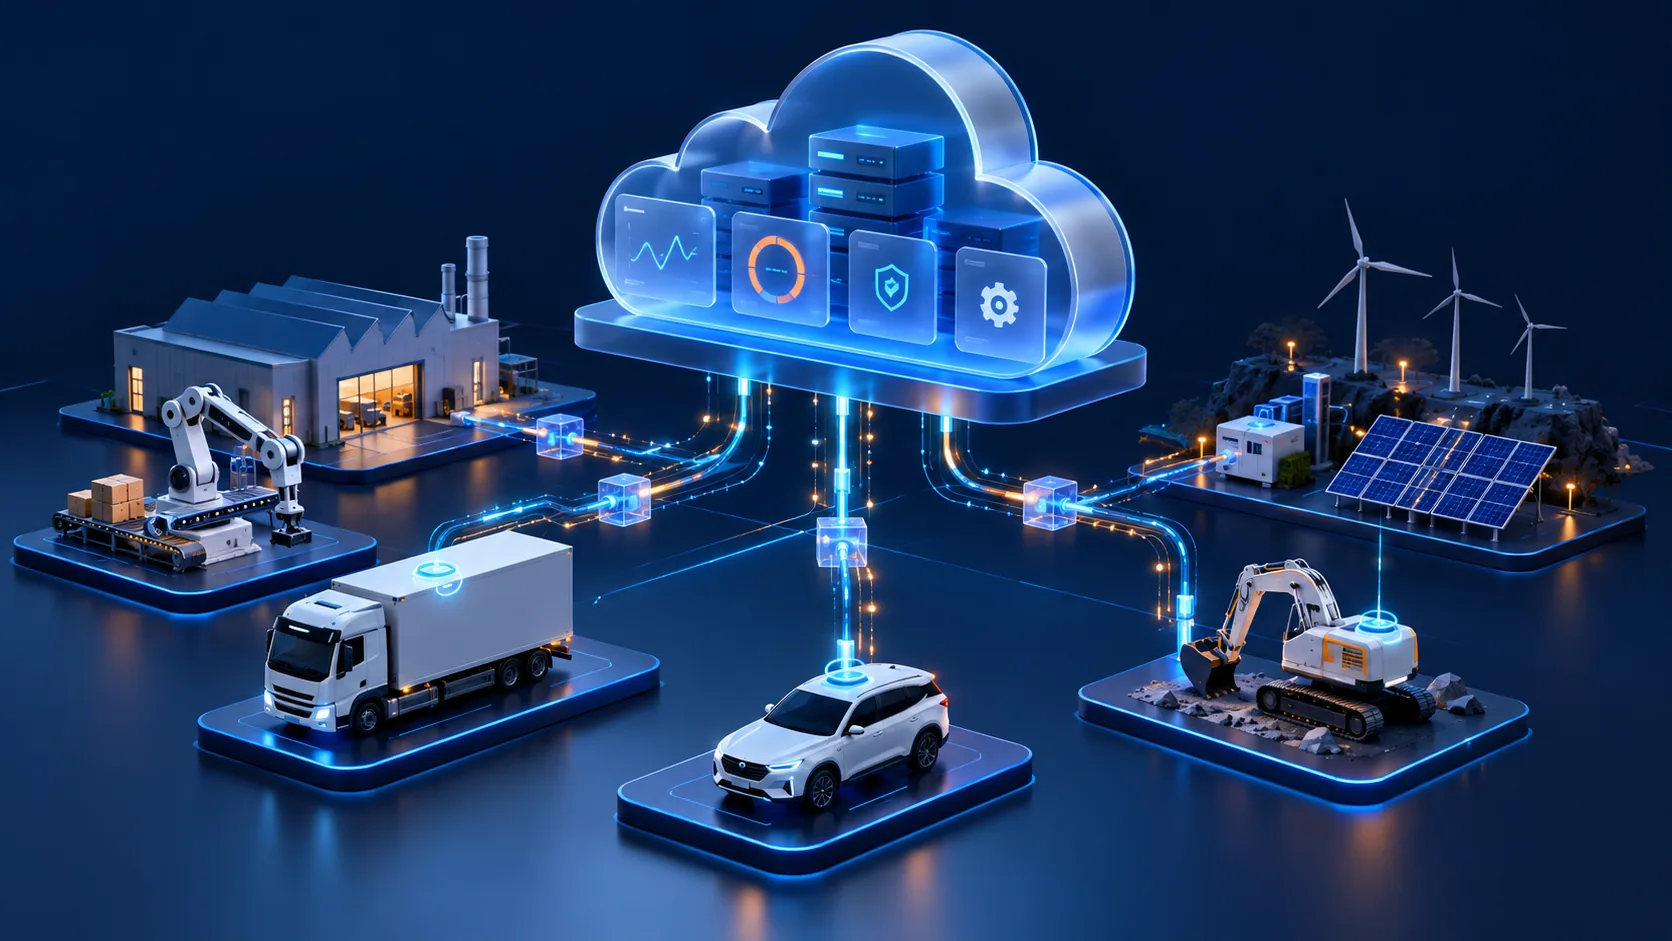
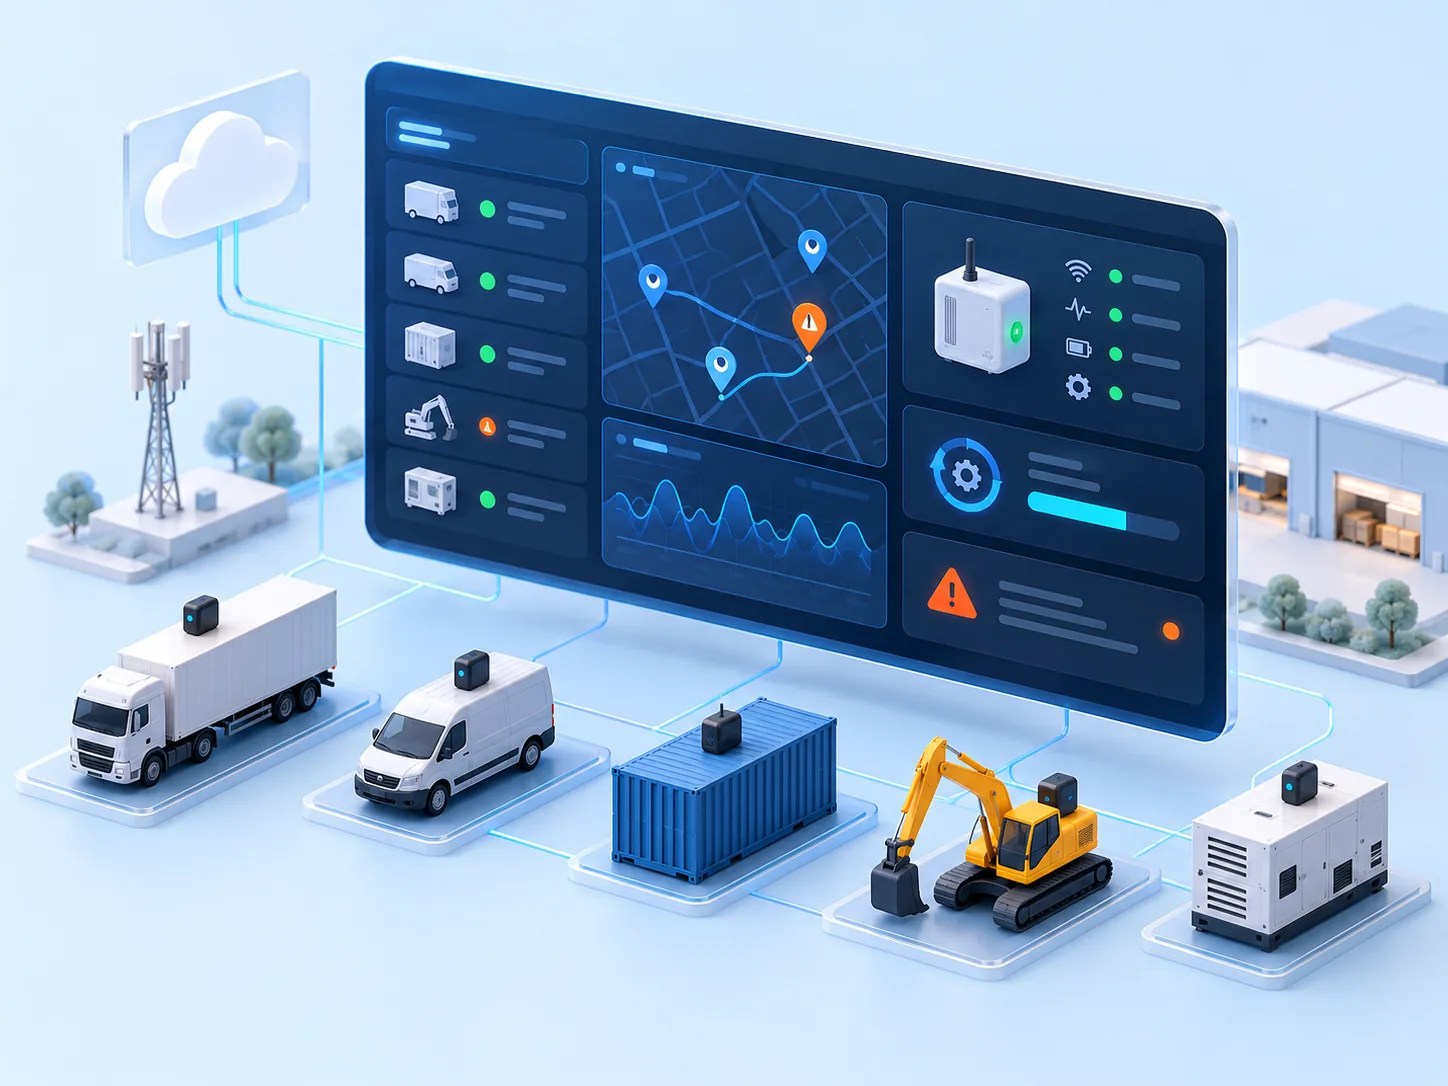
The backbone: device identity, secure connectivity, command and control, and tenancy that holds up when the product is sold through partners rather than direct.
RegistryMQTT / HTTPSMulti-tenant
Connected products · Software & AI
We build the layer between a connected device and the people who depend on it — provisioning, telemetry, the app in an installer's hand, the dashboard an operations team lives in, and the models that turn a stream of readings into something worth acting on.
The business problem
Most connected-product programmes do not stall on electronics. They stall when ten units become ten thousand, and nobody built the software to provision them, watch them, update them or explain what their data means.
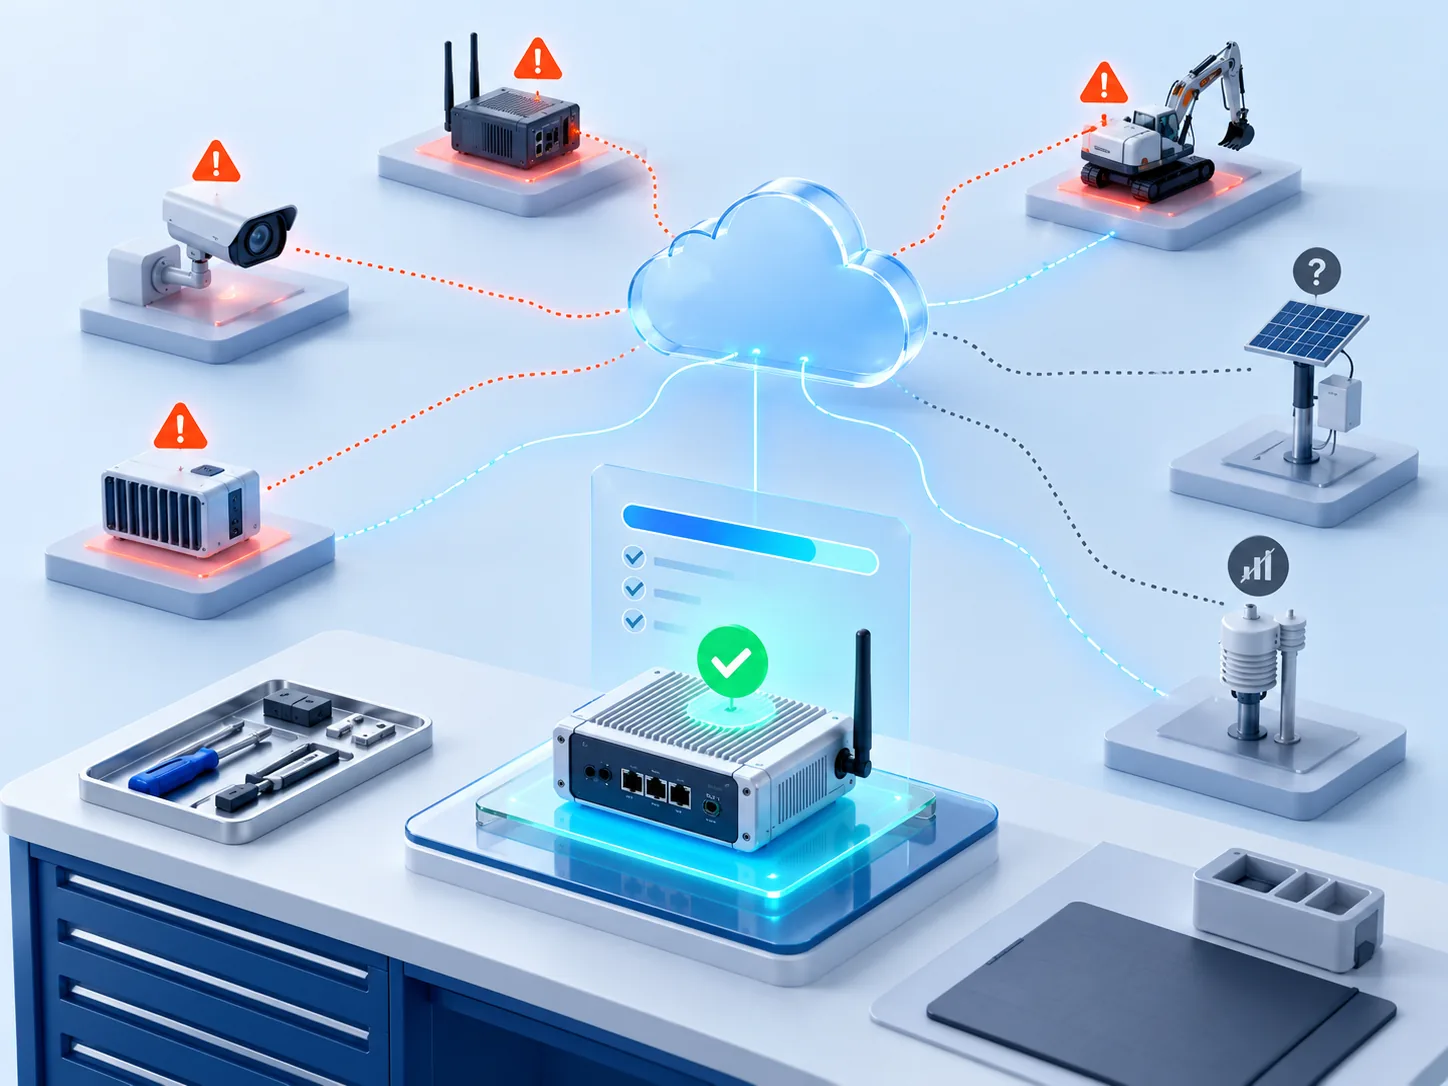
Commissioning a unit on site takes an engineer, a laptop and a phone call, because there is no app that does it.
Telemetry lands in a database nobody can query without writing SQL, so it informs nothing.
A fault is reported by a customer rather than detected by the platform, so every issue starts already late.
Firmware updates go out by hand, which means they effectively stop going out.
Each new device variant needs its own bespoke integration, so the tenth costs as much as the first.
The data that would justify the product's price is being collected and thrown away.
Our approach
A connected product is a distributed system that happens to have hardware at the edge. We design it that way from the start: one identity model for devices, one ingestion path for their data, one place where a human sees what the fleet is doing, and one mechanism for changing what the fleet runs.
That means the boring parts get built properly — provisioning, authentication, versioning, retries, back-pressure, offline behaviour on sites with unreliable connectivity. Those are what decide whether the product survives its second year.
AI comes after that, and only where the data supports it. Anomaly detection on a signal you have twelve months of is useful; a prediction built on three weeks of readings from four units is a demo. We say which one you have before anything is scoped.
Capabilities
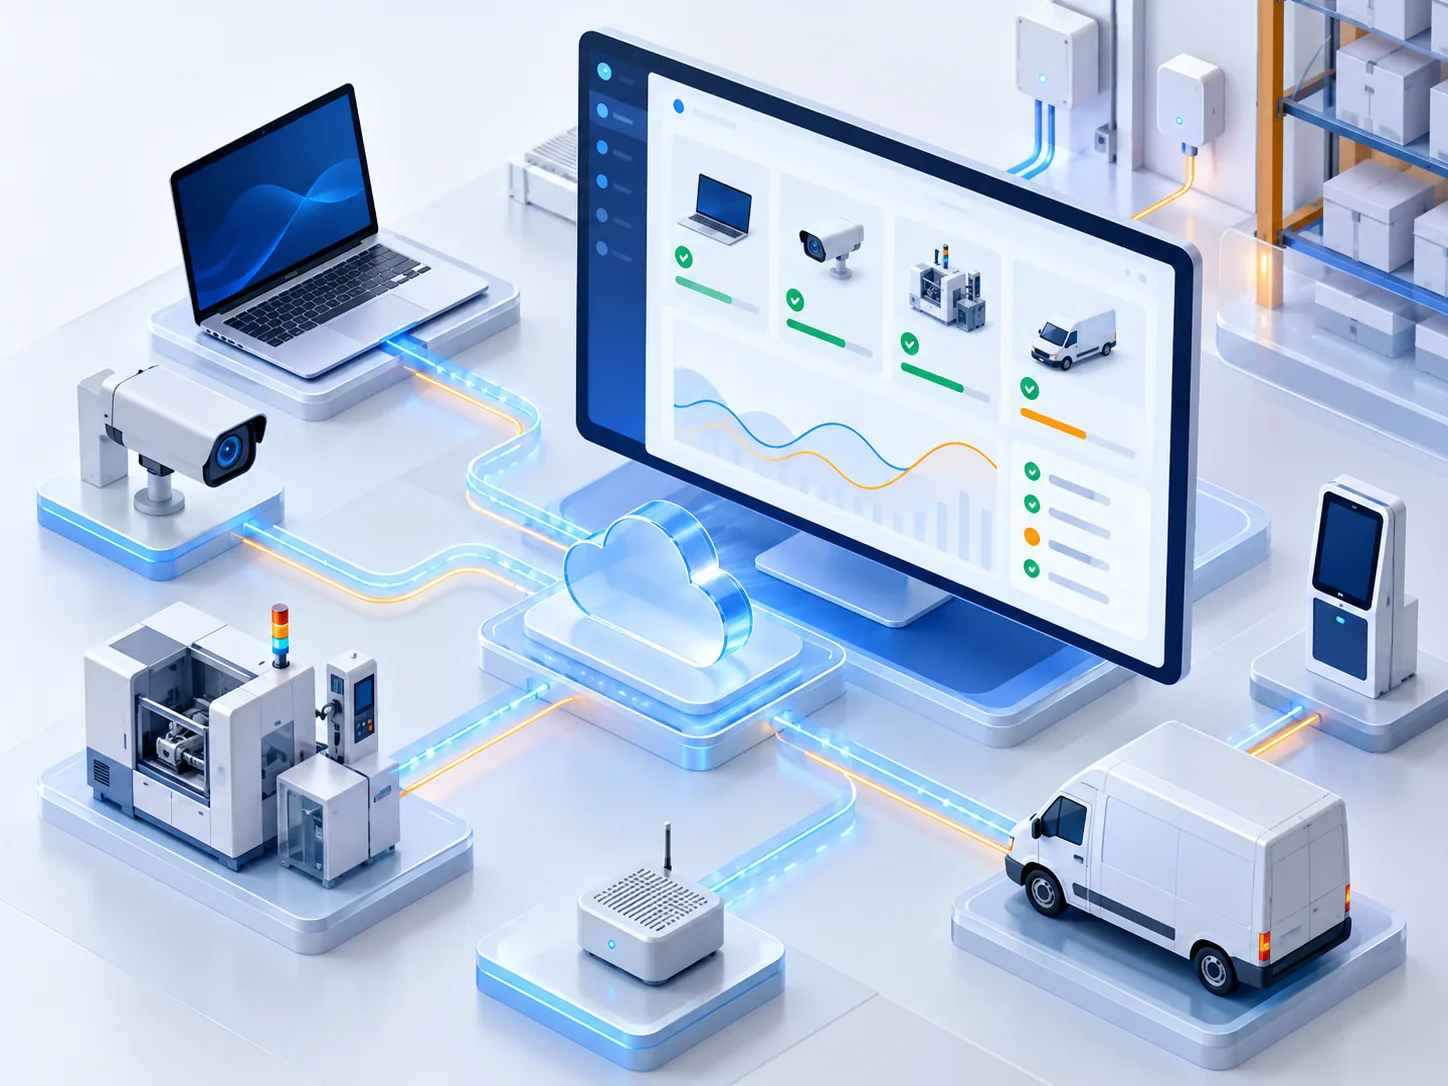
Programmes usually start with one device class and the operational view around it, then widen to the rest of the fleet once the shape is proven.
01
The backbone: device identity, secure connectivity, command and control, and tenancy that holds up when the product is sold through partners rather than direct.
02
The app the engineer actually opens on site — pair, configure, verify, photograph, sign off — designed for a basement with no signal rather than an office with fibre.
03
Web platforms for the teams who run the estate and, where the commercial model needs it, for the customers who own the devices.
04
Turning the stream into decisions: what is failing, what is drifting, what needs a visit this week rather than next quarter.
05
Connecting the fleet to the systems that bill, dispatch and support, so a detected fault becomes a scheduled job rather than an email.
Delivery model
Scope and sequence are agreed before engineering begins, and every stage is reviewable.
01
Device classes, connectivity reality, expected volume, who touches a unit and when. Designing for today's ten units is the most common and most expensive mistake in this category.
02
One device class, from provisioning through telemetry to a view a human reads. A thin complete path beats a thick partial one every time.
03
Get the installer app into real hands early. Site conditions — signal, lighting, gloves, time pressure — change the design more than any workshop will.
04
Collect and validate before predicting. Where the history does not support a model yet, we build the collection and say so rather than shipping a confident guess.
05
Extend to the rest of the fleet and document for the team who will operate it, including the runbook for the day something goes wrong at scale.
How we work together
Start with a conversation. Commit to scoped work only when a deeper review or a build is genuinely the right next step — and only once the scope is written down.
Start here — free call
01
Free30 minutes
One workflow, discussed with a solutions architect. What it costs you today, what is technically in the way, and whether anything further is warranted.
02
USD 5,0004 weeks
A scoped review when the picture is genuinely unclear — several systems, an unproven integration, or a decision nobody can size yet.
03
From USD 25,000Scoped per engagement
An agreed priority turned into working software, connected systems or a governed AI workflow, delivered in stages you can release and review.
Larger platform programmes start at USD 75,000. All figures are in USD and are starting points rather than quotes — scope, integration surface and the number of systems involved move the number. Commercial terms are always confirmed in writing before work begins.
Before we talk
No. We work alongside your hardware team or your manufacturing partner, and we are explicit about that boundary. What we take responsibility for is everything from the device's network interface inwards — provisioning, connectivity, data, applications, integrations and the AI layer on top.
Usually not. A retrofit programme is common: put the platform, ingestion and operational view in place around the fleet as it exists, then improve the device-side software as units are updated or replaced. The sequencing is different from a greenfield build, but the destination is the same.
It is assumed rather than treated as an edge case. Store-and-forward on the device, idempotent ingestion, explicit reconciliation and an app that works with no signal at all. A platform that only behaves on good connectivity will fail in exactly the sites that matter most.
Because we will tell you when it is not. Anomaly detection and condition monitoring need a meaningful history of labelled behaviour. If your fleet has not produced that yet, the honest engagement is to build the collection and the baseline now, and revisit the model when there is something to train on.
Keep exploring
Start with a conversation
Bring us the process that is slowing you down, the system that will not connect, or the platform that needs to evolve. We will tell you what we would do about it — and whether you need us at all.
Free · 30 minutes with a solutions architect · No obligation to commission an audit · sales@appnox.ai